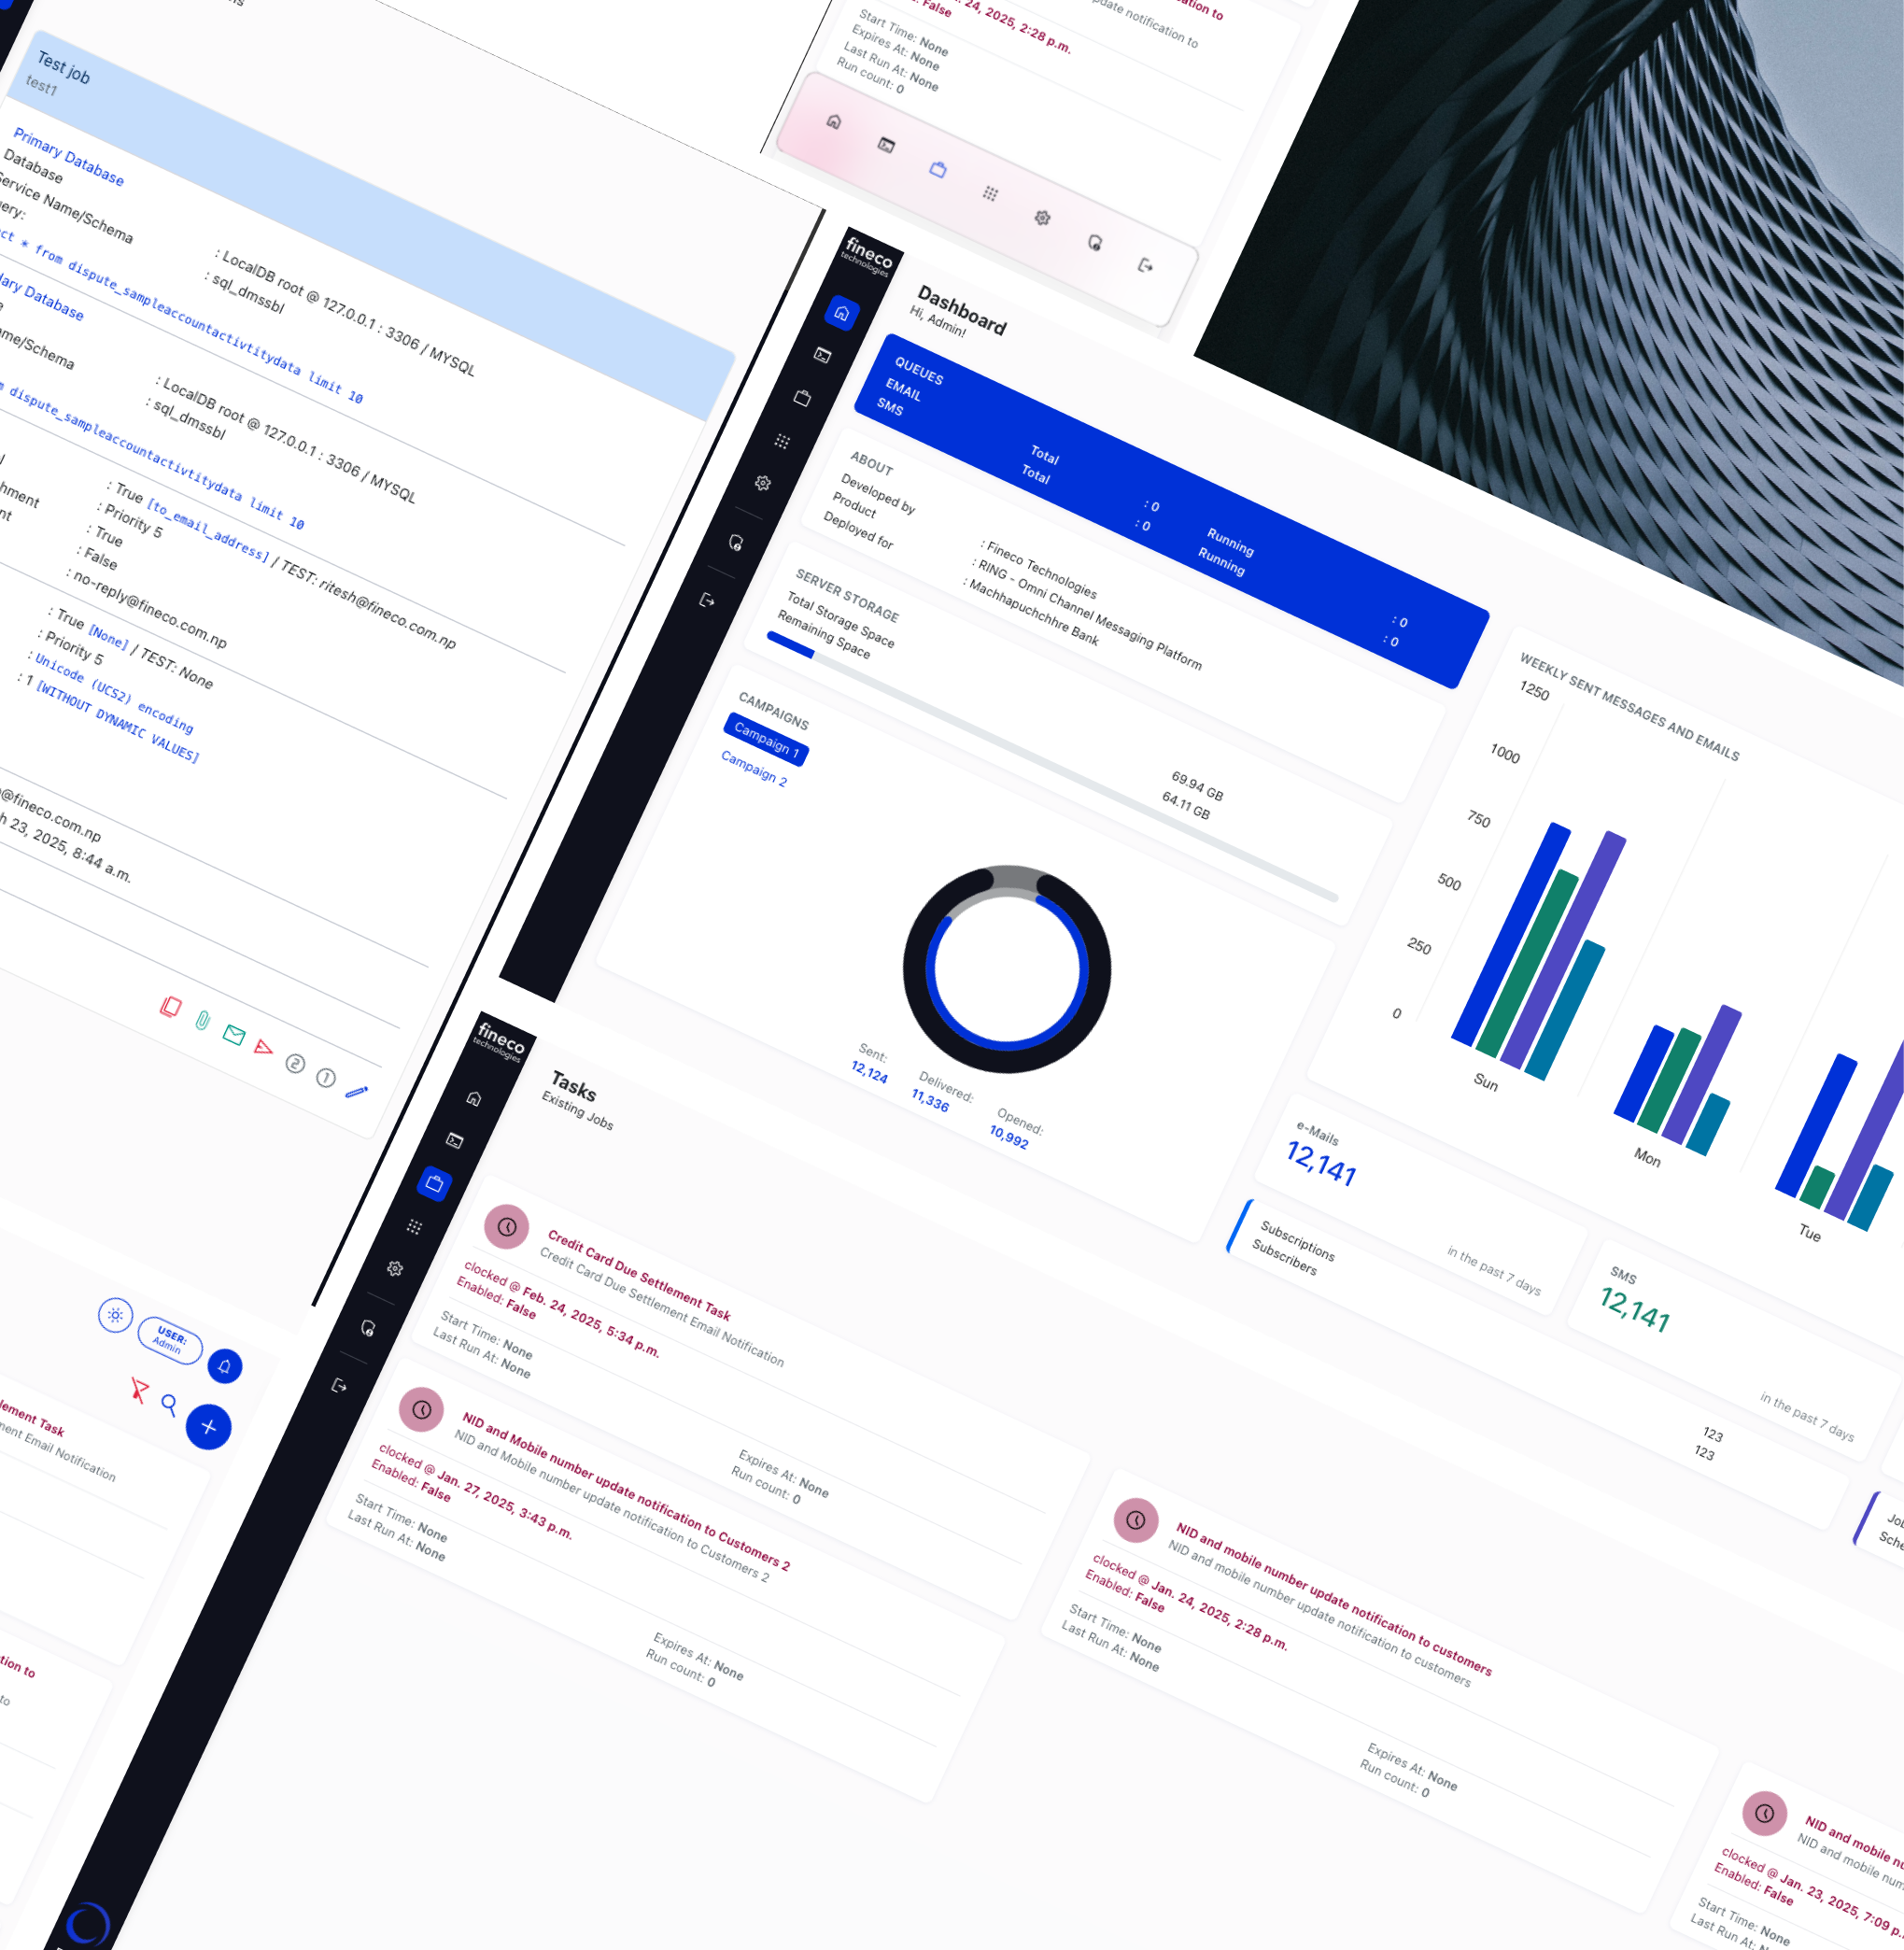
A distributed messaging platform built to deliver time-critical alerts and communications for a financial institution across every channel a customer might be reached on — email, SMS, and push — from a single, unified pipeline.
The system was built to solve a problem that becomes dangerous, not just inconvenient, in banking: when a customer needs to know something urgently — a fraud alert, transaction alert, OTP, or failed transaction — every second of delay is a second of exposure.
For a financial institution, a notification isn't just a UX convenience — it's often part of the security model itself. OTPs, fraud alerts, failed-login notices, and transaction confirmations all depend on the message reaching the customer before the moment it's relevant to has passed.
The system this replaced was slow by design, not by accident. Messages of every kind — critical fraud alerts and routine promotional content alike — moved through the same processing path, competing for the same resources.
A time-sensitive alert could therefore sit behind a batch of low-priority messages with no way to bypass that work.
That created a real operational risk. A roughly two-minute delay on an OTP or fraud alert isn't simply inconvenient — it's a window in which the system's own communication becomes too slow to be useful for the thing it exists to protect.
The core challenge was building a system where message priority was enforced through the architecture itself, while still supporting high throughput, dynamic content generation, multiple source systems, and multiple delivery channels.
Priority needed to determine how a message moved through the entire pipeline, not simply where it appeared inside one shared queue.
Throughput had to increase by adding workers rather than by increasing reliance on one central processing path.
Message content needed to pull customer and transaction information from different connected databases without hard-coding every new source and message combination.
Simple messages such as OTPs and heavier jobs such as generated account-statement PDFs needed to coexist without expensive content generation delaying time-critical traffic.
Email, SMS, and push needed to operate from one platform while preserving their different delivery behavior and failure handling.
The system needed to remain predictable during the exact events most likely to produce sudden messaging spikes, including fraud events and widespread service failures.
In effect, the system needed to behave less like a mail-merge tool and more like a real-time distributed dispatch engine, with message priority treated as a first-class architectural concern rather than a sort order.
I was involved in the architecture and development of the platform, with responsibility spanning the messaging pipeline rather than individual screens or endpoints.
The key architectural responsibility was making sure that no matter how much bulk or templated traffic was moving through the system, a critical alert could still be dispatched with effectively no delay.
Priority couldn't simply be a sort value inside one queue. Critical and bulk traffic needed physically separate processing lanes so a backlog of low-priority work had no path to interfere with urgent dispatch.
Multiple workers only improve throughput if shared queues, databases, and coordination don't become the next point of contention. The worker model had to scale while preserving the same latency guarantees for critical traffic.
Customer, transaction, and statement data lived across different systems. A dynamic mapping layer allowed new data sources and message types to be configured instead of requiring a new integration pipeline every time.
An SMS OTP and a generated statement PDF have very different processing costs. Content generation therefore needed to operate as a separate, pluggable stage so expensive work couldn't stall lightweight critical messages.
Email, SMS, and push each have different provider behavior, failure modes, and retry semantics. Channel-aware retry and failure handling ensured a delivery problem on one channel did not block or slow the others.
This project reframed how I think about latency in distributed systems. It's tempting to treat “make it faster” as an optimization problem solved after the system already works.
Here, latency was the requirement. A fraud alert that arrives in two minutes isn't simply a slower version of the correct behavior — it's different, incorrect behavior entirely.
That meant the real engineering work wasn't tuning an existing pipeline. It was recognizing that different message priorities needed structurally different paths through the system from the beginning.
It also changed how I think about queues. Rather than one shared queue with priority flags, physically separate queues for critical and bulk traffic meant a backlog on one could never bleed into the other.
The dynamic mapping layer reinforced the same architectural idea from another direction: treat source systems and delivery channels as interchangeable inputs and outputs, so adding a new combination doesn't become another integration project.
I'm always open to conversations around interesting problems, ideas, and opportunities to work together.
Reach out at hi@riteshr.com.np